// our services
AI reputation management
 Google moet berispte arts verwijderen uit zoekmachine (Trouw, 2019)
 Dutch surgeon wins landmark 'right to be forgotten' case (The Guardian, 2019)
 'Vergeetrecht' wordt op het web lang niet altijd toegekend (NRC, 2017)
 Rechter verbiedt amateurbeelden zonder toestemming op pornosite (AD, 2022)
 Comeback Ali B strandde nog voor hij het podium op kon (RTL Nieuws, 2026)
// AI reputation management
Improve your AI reputation: shape what LLMs such as ChatGPT, Gemini and Claude say about you
AI platforms answer more and more questions about companies and people directly, without the user ever clicking on a search result. What AI says about you increasingly determines how you are seen by customers, recruiters, journalists and investors. We correct inaccurate output, design and carry out GEO strategies, and build the sources that AI cites.
// ai baseline
Find out what ChatGPT, Gemini and Perplexity say about you now
Request a free AI baseline report: for each platform we show what is currently said about you, and what is wrong.
Request a free AI baselineWhat is AI reputation?
AI reputation is the picture that AI chatbots such as ChatGPT, Gemini, Copilot and Perplexity give of a company or person, based on their training data and on the sources they consult during a conversation. Unlike search engines, AI platforms give a direct answer rather than a list of options. What AI says about you often determines the entire impression a user is left with.
Generative Engine Optimisation (GEO) is the discipline concerned with influencing how AI platforms answer questions about a subject. Just as SEO aims for visibility in search results, GEO aims for visibility in AI answers: as a cited source, as a factual mention, or as a leading voice on a subject.
// how it works
How AI platforms build their answers
To understand how you can shape your AI reputation, you need to know how AI platforms arrive at their answers. Broadly speaking, there are two mechanisms:
Training data.
Models such as GPT, Gemini and Claude have been trained on vast amounts of text from the internet. Whatever that training data said about you at the moment the model was trained forms the basis of what the model "knows" about you. Training data is a snapshot: models know nothing of developments after their knowledge cutoff, unless they are actively retrained.
Retrieval-augmented generation (RAG).
More and more AI platforms, including Perplexity, Copilot, ChatGPT with web search and Gemini with its Google integration, combine their training data with live search results. The moment you ask a question, the platform looks up current sources and uses them to formulate the answer. Which sources it uses depends on authority, citability and consistency, much like the way Google's algorithm ranks content.
In practice, both mechanisms work together. An AI answer about you is a mix of what the model found in its training data and what it retrieves at the moment of the question. Shaping your AI reputation is therefore not a single tactic but a layered approach that targets both future training data and live retrieval sources.
// core services
1. AI correction requests
Since 2024 we have been submitting formal correction requests to the major AI providers: OpenAI (ChatGPT), Google (Gemini), Anthropic (Claude), Microsoft (Copilot), Grok (xAI) and Perplexity. A correction request addresses factual inaccuracies, harmful associations or outdated information that keeps recurring in a platform's output.
Our legal reasoning rests mainly on Article 17 GDPR (the right to be forgotten), supplemented where relevant by Article 10 GDPR (personal data relating to criminal convictions and offences).
How a correction request works differs per platform. OpenAI has a formal privacy procedure for removing personal data from model output. With Google and Microsoft, there are routes through privacy and legal correspondence. With Anthropic and Perplexity, we work through direct legal correspondence. In every case, success depends on the substance of the argument, the evidence and the timing relative to model updates.
A correction request rarely leads to an immediate change across all model versions. It works cumulatively: new model versions pick up corrections, retrieval systems take them into account when choosing what to cite, and together with the other two core services this produces a lasting improvement.
2. Designing and carrying out a GEO strategy
A GEO programme at MediaMaze is a structured approach to shaping the AI output about a company or person over a period of 6 to 12 months. We work with five elements, partly in parallel and partly iteratively:
1. AI baseline report. We map what the four major AI platforms currently answer about you on the most likely user questions. Which facts are correct, which are outdated or wrong, which sources are cited and which are missing. This report is also our entry-level offer for new clients.
2. Source mapping. Which authoritative sources feed the current AI answers? Which sources are missing that ought to be there? Which sources can be changed through correction or update, and which only through suppression?
3. Content roadmap. Based on the source mapping, we design a plan: what needs to be published, updated or corrected, where, and in what order. The roadmap is not fixed; we adjust it every month based on what the measurements show.
4. Execution. Execution runs largely through our digital PR practice: news stories, background pieces and expert contributions in authoritative media. Supplemented where relevant by correction requests (core service 1) and source creation (core service 3).
5. Measurement and adjustment. Continuous monitoring of AI output through Reptor.ai shows what is moving. On that basis, we adjust the roadmap every month.
3. Creating AI-friendly sources
In their answers, AI platforms cite specific sources. Which sources they choose depends on authority, citability and, for retrieval systems, how recent the source is.
In practice, online news and background journalism make up the bulk of what AI platforms use as sources for questions about companies and people. A good background article in an authoritative business outlet or trade platform is cited more often in AI answers than ten scattered mentions on smaller sites combined.
Our approach to creating AI-friendly sources therefore runs largely in parallel with our digital PR approach: we place background articles, expert contributions, profiles and interviews in the media that carry weight both in search results and in AI output. The difference lies in how we shape those placements, with citable blocks, structured facts and authoritative context, so that LLMs also pick them up and cite them.
In addition, where it is justified on the merits and feasible, we work on structured source references on platforms such as Wikipedia and Wikidata, industry databases, and structured data (schema.org) on the client's own domain.
Our role as an early adopter in the Netherlands
Since 2024 we have been submitting correction requests to the major AI providers as a matter of routine. Since spring 2025 we have been continuously and systematically monitoring what the four major AI platforms say about our clients, using our own platform Reptor.ai. We are the first Dutch agency to offer AI correction requests as an integrated service, and we belong to a small group of firms in the Netherlands that practise GEO as day-to-day work rather than treating it as a concept.
We do not claim a world first. GEO as a concept has been established internationally since 2023. What we do claim is this: structural hands-on experience with right-to-be-forgotten requests to search engines since 2016 and with AI correction requests since 2024, structured AI monitoring since spring 2025, and an integrated range of services in which AI reputation is linked to traditional ORM, legal and editorial work.
// seo vs geo
SEO and GEO: overlap and differences
Many clients ask whether GEO is simply a new name for SEO. It is a fair question. Good SEO often works in the same direction as good GEO: both call for authoritative sources, high-quality content and consistent mentions. A strong SEO layer is therefore often a good foundation for GEO. But there are clear differences in where the focus lies and how you measure success.
| Aspect | Traditional SEO | GEO |
|---|---|---|
| Goal | Top position in search results | Source position in the AI answer |
| Signals | Backlinks, content relevance, technical SEO | Citability, source authority, structured facts, NAP consistency |
| Lead time | 3-9 months | 6-12 months |
| Measurement | SERP position, organic traffic | AI output sampling per platform |
| Content format | Long-form, optimised for keywords | Citable blocks, expert contributions, structured facts |
In practice, we do both at the same time within one programme. A good SEO position in Google often also earns a good source position in retrieval-based AI answers. The difference lies in where we put in extra effort specifically for results in AI.
// in practice
Cases (anonymised)
Years ago, a business executive was a suspect in a criminal case. During that period, several news reports appeared in which he was mentioned in a negative context. He was eventually fully acquitted, but the old reports kept ranking high for his name in Google, and ChatGPT repeated the suspicion as fact without mentioning the acquittal.
We worked on three tracks at once: right-to-be-forgotten requests for the search results under Article 17 GDPR (unlawful processing of personal data relating to criminal offences), formal correction requests to OpenAI and Google substantiated with the acquittal, and at the same time a new content layer of background articles and profiles in authoritative business media describing the executive's current situation. The result: the old reports have been removed from the relevant search results, and AI answers are now dominated by the current context, including a correct mention of the acquittal.
Years ago, a major news article described a Dutch company as an organisation with a culture of fear under its leadership at the time. Since then, the leadership had been completely replaced, the culture had been transformed, and internal employee satisfaction surveys had improved considerably. Even so, the old article kept ranking high for the company name, and AI answers invariably brought up a reference to the past without mentioning the current situation.
We deployed a mixed GEO approach: several new background articles in authoritative business media in which the current leadership had their say, expert contributions on trade platforms about the cultural transformation, profiles on international authoritative sources and, after we found that a specific image from the old article was being reused unlawfully on other sites, DMCA procedures to have the image removed. Result: the current culture and leadership now dominate both Google results and AI answers, and the old article has moved to page 2 of Google.
// frequently asked questions
Answers to frequently asked questions
SEO aims for a high position in search results. AI reputation management targets how AI platforms answer questions about you: as a cited source, as a factual mention, or as the dominant voice on a subject. SEO and AI reputation overlap considerably (authoritative sources work for both), but AI reputation calls for extra effort on citability, structure and correction requests to AI providers.
Yes. AI models hallucinate: they produce plausible-sounding information that is factually wrong. According to independent research, the hallucination rate on questions about people, companies and legal matters is substantial. Outdated information, confusion between different people with the same background, and repetition of unreliable sources are the most common problems.
Yes. OpenAI has a formal privacy procedure for removing or correcting personal data in ChatGPT's output. You submit the request through a privacy form, explaining which output is factually wrong and why. Experience shows that the substance of the argument and the evidence are decisive. A rejected request can often be resubmitted with a revised argument; since 2024 we have built up experience with the wording that does work with OpenAI.
Yes. For Gemini, corrections go through Google's privacy and legal channels, partly via the same GDPR routes we use for search results. Your request must show that the output contains inaccurate or outdated personal data. The substance of the argument and the evidence decide whether it succeeds, and a rejected request can be resubmitted with a revised argument. We have had experience with the Google procedure since 2024.
Yes. At Microsoft, a correction for Copilot goes through the privacy and legal correspondence channels. We set out which personal data recur in the output in an inaccurate or harmful way, and on what grounds removal or correction is required. As with the other platforms, the argument and the evidence are decisive, and a rejected request can often be resubmitted with revised substantiation.
Yes. With Anthropic, we use direct legal correspondence to correct factual inaccuracies or harmful associations in Claude's output. We support the request with the relevant GDPR grounds and evidence. The substance of the argument decides whether it succeeds, and a rejected request can be resubmitted with a revised argument.
Yes. Because Perplexity relies heavily on retrieval (live sources), we work here both through direct legal correspondence with Perplexity and by correcting or updating the underlying sources the platform cites. That is often the quickest route to a visible result. The argument and the evidence remain decisive for the success of the request.
Yes. For Grok, we submit correction requests through direct legal correspondence with xAI, on the same GDPR grounds as with the other providers. Grok is a relatively new platform, so its procedures are less settled, but here too the substance of the argument and the evidence are decisive, and a rejected request can be resubmitted.
It differs per platform and per type of correction. For retrieval-based answers (Perplexity, Copilot, ChatGPT with web search), a correction can become visible within weeks, provided the underlying source has been updated. For corrections that have to find their way into training data, it takes until the next major model update, sometimes months to a year. That is why we always work on several tracks at once.
Yes. Wikipedia is one source among many and certainly not always feasible or necessary. In our practice, GEO works largely through online news and background journalism: authoritative media that carry weight both in Google and in AI output. For smaller clients this is often enough, provided the programme is set up properly.
A written report showing, per platform (ChatGPT, Gemini, Copilot, Perplexity), what is currently being answered about you or your company on the most likely user questions. We highlight factual inaccuracies, outdated information, missing context and the sources cited. The report is the basis for any follow-up, or shows that a follow-up is not needed.
About the author
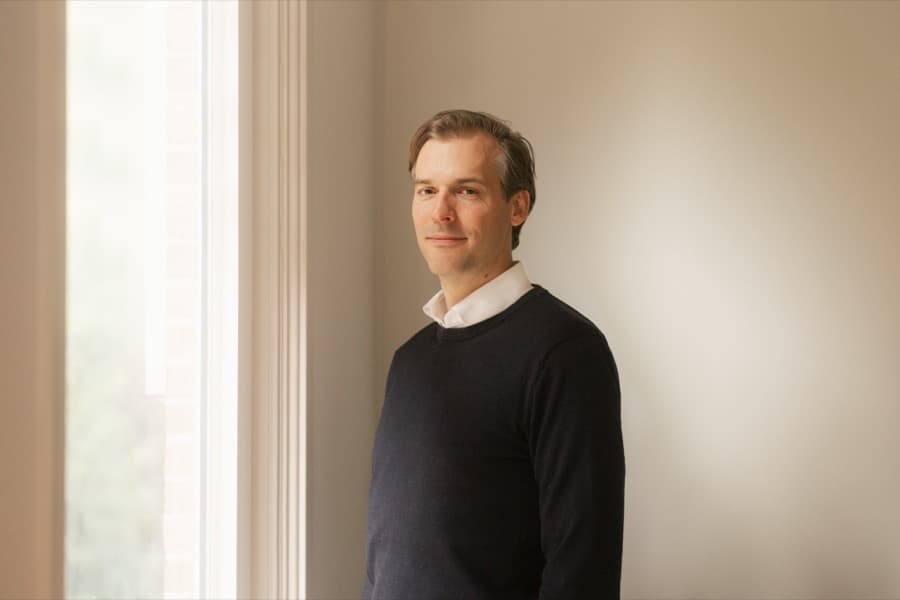
Willem van Lynden, founder of MediaMaze (Amsterdam, 2012). 15 years of experience in online reputation management, with more than 500 right-to-be-forgotten cases to his name and a success rate above 90%. Active with formal correction requests to AI providers since 2024. Board member of Stichting Stop Online Shaming. A sought-after expert on AI, online reputation and privacy on television and radio and in print media.
// free analysis
Dealing with an inaccurate or negative online image?
An old news story, an unfair review or a story that AI gets wrong: we take stock of the situation and look at how it can be improved. A one-off analysis, free of charge.
Get the free analysisLast updated on · published on